


TL;DR
- Cleaning each spreadsheet on its own misses people who appear in more than one file.
- Combine the files into one list before you look for duplicates.
- Line up column headers and formats first, so the same field matches across files.
- A combined file can be clean and still hold people already in your CRM.
- Dedupely combines spreadsheets with the same headers, merges duplicates across them and exports clean records.
Data rarely arrives in one file. Marketing has a list from last month's event, and a sales rep keeps prospects in a personal spreadsheet. A branch office sends its customer list before a CRM rollout.
Each file can look clean on its own. Put them together and the same person may show up three times, with a different email, spelling or phone format in each.
In this post, you'll see why cleaning file by file misses those duplicates and how to line up headers before you combine anything. You'll also see how to decide which fields prove a match, which value wins, and what to check once the data reaches your CRM.
Why cleaning each file alone misses duplicates
Spreadsheet tools remove duplicates inside the range you select. A person listed once in the event list and once in the sales list is unique in both files. Neither cleanup catches them.
That overlap between files is the part a file-by-file cleanup can't see. It's also where the duplicates that reach your CRM tend to come from, because each file passes its own check.
Line up the headers before you combine
Files from different teams describe the same data in different ways. Before you combine them, make each column mean the same thing in every file.
Give each field one name
One file says "Email", another "E-mail address" and a third "Work email". Pick one name and use it as the header in every file, so the headers are the same.
This matters because many tools combine files by header name. Microsoft's Power Query, for example, appends tables based on column header names, and adds empty values when a column doesn't match. Two names for one field become two half-empty columns.
Split or join fields so they match
One file has "Full name" and another has first and last name in separate columns. Choose one shape and convert the other files to it. The same goes for "Company" in one file and "Account name" in another.
Use the same formats
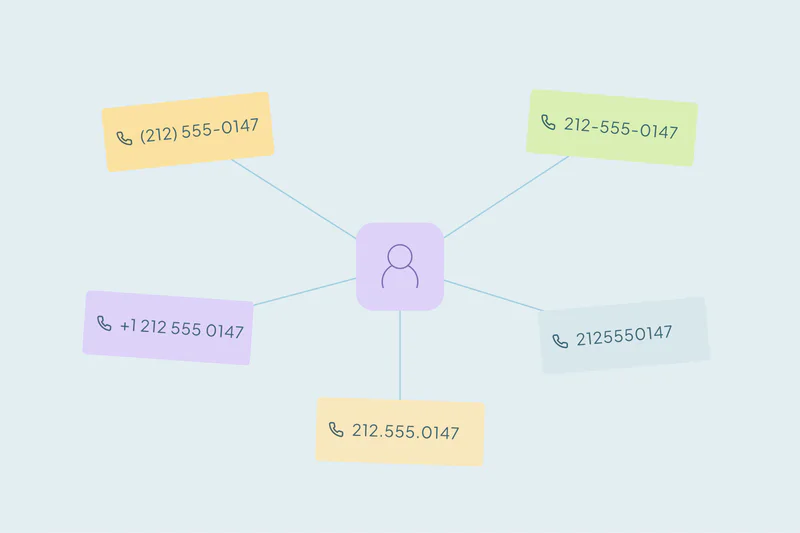
Phone numbers with and without country codes, extra spaces and mixed capitalization all stop two values from matching. Fix them in each file first. Our post on tools to clean a CSV before an import covers how spreadsheet apps and other tools handle this.
Add a column for the source
Add a column that says which file each row came from. It helps you decide which value wins later, and it lets you trace a merged row back to its file.
| Event list | Sales spreadsheet | Branch list | Combined header |
|---|---|---|---|
| E-mail address | (none) | ||
| Full name | First, Last | Name | First name, Last name |
| Organization | Company | Account name | Company |
| (none) | Phone | Mobile | Phone |
| (none) | (none) | (none) | Source file |
Combine the files into one list
Once the headers match, stack the files into one list. In Excel, Power Query's Append combines the rows of two or more tables into one. In Google Sheets, the IMPORTRANGE function pulls a range of cells from another spreadsheet.
IMPORTRANGE brings a range into a sheet; it does not stack every source or remove duplicates by itself. Align the columns, combine the imported ranges into one table, then apply the match and merge decisions.
For a few small files, pasting one below the other works too. Whatever you use, work on a copy and keep the original files untouched.
Decide which fields prove a match
Start with the obvious duplicates: exact matches on email for people, or website domain for companies. Those are the ones you can merge with the least doubt.
Then look at rows without a shared email. Name plus company, or name plus phone, can catch the same person listed differently. Our guide to which fields to match on covers when each one is strong and when it misleads.
What counts as a duplicate is case by case. A branch may treat a person at two locations as two contacts, while sales sees one. Agree on it with the teams that sent the files before you merge.
Decide which value wins before you remove anything
Removing duplicate rows deletes data. If the row you lose held the only phone number, that number is gone.
Decide field by field which value to keep. The source column helps here: you might trust the branch list for phone numbers and the event list for job titles.
- Newest value: useful when files were collected at different times.
- Most complete value: useful when one file has fuller records.
- Value from a trusted file: useful when one team owns a field, like billing contacts.
Whatever you pick, a blank should never replace a value that exists in another row.
Check the clean list against your CRM
A combined file can be free of duplicates and still contain people who are already in your CRM. They may be there under another email or a misspelled name.
After the import, look for duplicates in the CRM using the same fields you matched on in the file. Lists from events and vendors are a common source of these, which we cover in how event and purchased lists create CRM duplicates.
If you import several files a month, agree on who combines and checks them. When everyone imports their own file, the overlap between them ends up in the CRM.
Several spreadsheets, one clean list
| Step | What to decide |
|---|---|
| Headers | One name and one shape for each field, plus a source column |
| Formats | One format for phones, names, countries and spacing |
| Combine | One list, with the original files left untouched |
| Match | Obvious duplicates first, then name with company or phone |
| Merge | Which value wins in each field, with blanks never winning |
| CRM | Which fields to match on once the records are imported |
How Dedupely finds duplicates across your spreadsheets
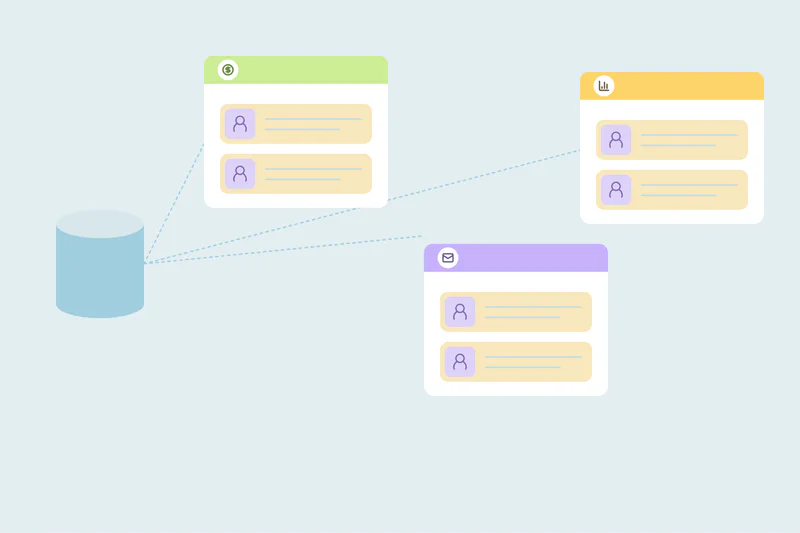
In Dedupely, you can combine several spreadsheets into one list when they have the same headers, and CSV uploads are unlimited. You build duplicate searches across the combined rows, set rules for which value wins, preview each merge and download the clean records. Once those records are in your connected CRM, Dedupely finds duplicates against your existing records there too.
Clean the overlap before it reaches the CRM
Duplicates across spreadsheets hide in the overlap between files. Cleaning each file on its own leaves that overlap untouched, so the same person reaches the CRM two or three times.
Lining up the headers, combining the files and deciding which value wins turns several lists into one. A check in the CRM after the import catches the people who were already there.
References: Microsoft: Append queries; Google: IMPORTRANGE.
Frequently asked questions
How do I find duplicates across multiple Excel files?
Combine the files into one table first, then look for duplicates in the combined list. Rename columns so the same field has the same header in every file, since Power Query appends tables by header name. Add a column for the source file, then match on email or name with company.
Can Google Sheets find duplicates across different spreadsheets?
Not directly, since Remove duplicates works on the range you select. Bring the data into one sheet first, for example with the IMPORTRANGE function, which imports a range of cells from another spreadsheet. Once all rows sit in one range, you can look for duplicates across them.
How do I combine spreadsheets with different column headers?
Rename the columns so each field has one name in every file, then combine them. Split or join fields that differ in shape, such as a full name versus first and last name. Columns with different names don't line up, so the combined list ends up with half-empty columns.
Which column should I use to find duplicates across spreadsheets?
Start with email for people and website domain for companies, since exact matches there are the least doubtful. For rows without a shared email, combine fields such as name plus company or name plus phone. What counts as a duplicate is case by case, so agree on it with the teams that sent the files.
Should I remove duplicates before or after importing into a CRM?
Do both: clean the combined spreadsheet before the import, so the file doesn't bring its own duplicates in. Then check the CRM after the import. A clean file can still contain people who already exist there under another email or a misspelled name.

 Or sign up with Google


 HubSpot Marketplace












