


TL;DR
- Deduplication often stalls after the first look, because the first merge feels risky.
- A cleanup moves faster when one person owns it and has a default first step.
- Know what a duplicate is in your CRM and what the merged record should keep.
- Merge the duplicates you're sure of first, and review unclear sets before deciding.
- Dedupely Intelligence shows your duplicates with no setup, so you can preview each merge first.
Many teams connect their CRM, look at the duplicates and then stop. The list is long, the first merge feels like a risk, and nobody is sure where to begin.
That pause is common, and it's understandable. Nobody wants to mess up the data or be the person who merged the wrong records.
Weeks pass, new duplicates arrive, and the list only gets longer. The way out is to make the first step small and obvious. In this post, you'll see why deduplication stalls, how Dedupely Intelligence gives you a first step and what to decide before merging.
Why deduplication stalls after the first look
From what I've seen, teams often stop at the first decision. Once it's made, the next ones get easier.
The first merge feels risky
Merges in many CRMs are permanent. Before the first one, it's natural to worry about losing a phone number, an owner or a deal history.
There's also a personal side. If something goes wrong, someone has to explain it, and nobody wants to look bad in front of sales.
Nobody wants to own it
Deduplication sits between teams. Sales lives with the duplicates, marketing creates some of them, and RevOps or an admin gets asked to fix them.
When nobody is in charge, everyone waits for someone else to make the first call.
There are too many places to start
Should you start with contacts or companies, email or name, exact matches or near ones? Each choice seems to need another one first, so the project stays at the planning stage.
29% of teams said cleanups put them at risk of overwriting customer statuses, losing linked records or merging the wrong accounts.
Make the first step a default one
The easiest way past a stalled start is to remove the first decision. Dedupely Intelligence is that default step: you open it and look at the results.
No match settings to choose
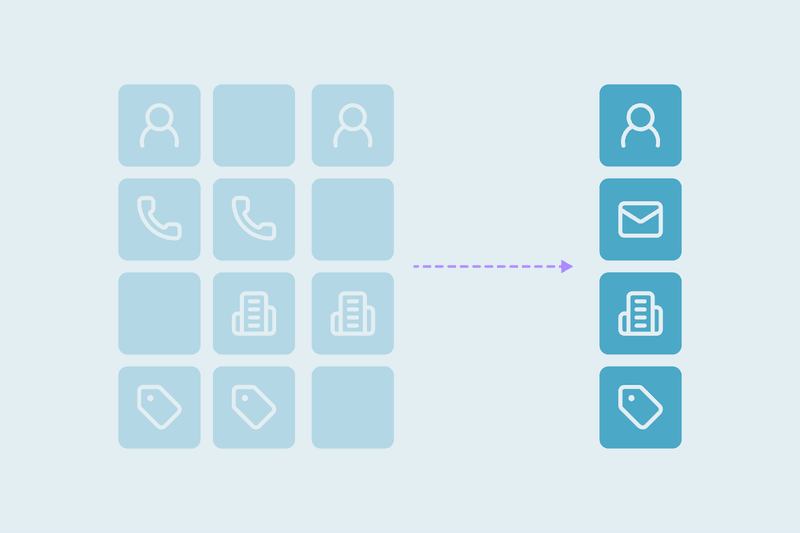
Dedupely Intelligence is matching built with AI that finds complex duplicate patterns without any match settings. You don't pick fields, match types or filters before you see anything.
Scans run automatically once your CRM is connected. It covers contacts, companies and leads for now. Yearly plans include it in full; on other plans and in the trial, you see a preview of its results.
Your CRM data stays private
AI is used only to design the matching logic. The matching itself runs as fixed code on Dedupely's infrastructure, and CRM data is never sent to outside AI models.
Results show you what you're dealing with
The results show duplicate sets you may never have thought to search for. Even before you merge anything, they tell you which kinds of duplicates your CRM holds.
What to do with the first results
From the results, there are two ways forward. Many teams use both.
Start merging what you're sure of
Begin with the sets you'd merge without a second thought. Often these are the obvious ones, such as the same person with the same email and name.
Preview each merge before it runs. A few clean merges build more confidence than any amount of planning.
Use the results as inspiration for your own searches
The results also show you patterns. Maybe many duplicates share a phone number, or company names differ only by "Inc." or "LLC".
Those patterns tell you which duplicate searches to build, and how loose or strict each field should be.
Review what's unclear, reject what isn't a duplicate
Some sets won't be clear at first. Leave those unmerged until you've decided what counts as a duplicate in your CRM.
Other sets won't be duplicates for your team. If you're certain, reject the match, and it won't appear in your searches again.
Know what a duplicate is, and what the merge should keep
What counts as a duplicate is case by case. What one team considers a duplicate, another may not.
Define the duplicate
Look at what makes two records the same in your CRM, and where records overlap. Two companies on one domain may be one account, or two branches you keep apart.
Once you know that, you can set how strictly each field should match.
Define the merged result
Decide what the surviving record should look like. Which record is the primary one: the oldest, the newest or the one with the most data?
Then decide field by field which value wins. Owner, lifecycle stage and email opt-out usually deserve the most attention.
Built-in safety for a first merge
Dedupely Intelligence is set up to keep a first merge small and visible.
| The worry | What's in place |
|---|---|
| Merging thousands of records by accident | No automatic merging and no database-wide "Select All" |
| Merging records that look alike but aren't | Risky matches, like very large sets or example data such as test@test.com, are held back from the main results |
| Losing the right values | Your choice of which record survives and which value wins applies, and you preview each merge |
| Losing history | Activities and associations move to the surviving record |
| Needing to check a merge later | Every merge is recorded in a history you can export as a CSV |
Merges can't be undone: they happen directly in your CRM, and most CRMs can't undo them either. Most Dedupely merges can be undone for 30 days, but treat every merge as permanent. The exported history keeps the original values, so records can be recreated if needed. See how to undo a merge.
Get help from people who do this every day
You don't have to make the first decisions alone. Dedupely's Customer Success team sees and solves duplicate problems every day.
Customer Success is unlimited on every plan and the trial, by Zoom call, chat or email. Bring your first results and your doubts, and work through the first merges together.
How to take your first step with Dedupely Intelligence
Connect your CRM, open Dedupely Intelligence and see the duplicates it finds in contacts, companies and leads, with no setup. From there, preview and merge the sets you're sure of, reject false matches and use the patterns to build your own duplicate searches.
The first merge is the hardest one
Deduplication often stalls at the start: the first merge feels risky, nobody owns it and every choice seems to need another one first. A default first step removes most of that weight.
Once you see the results, the next moves get smaller. Merge what you're sure of, review what's unclear and reject what isn't a duplicate. What you learn decides what a duplicate is and what each merge should keep.
Frequently asked questions
Where should I start with CRM deduplication?
Start with the obvious duplicates, usually exact matches on fields like email for contacts and domain for companies. Merge a small batch you're sure of and check the results. Then decide what counts as a duplicate in your CRM, and use that to build looser searches for the rest.
Why is merging duplicates in a CRM scary?
Because merges in many CRMs are permanent, and a wrong merge can lose an owner, a phone number or linked records. It's also visible: someone has to explain it. Previewing each merge, starting small and keeping an export of the original values make the first merges much safer.
Who should own CRM deduplication?
One person should lead it, usually a CRM admin or someone in RevOps, with one or two backups. Sales, marketing and support all have a stake, so agree on what counts as a duplicate together. A single owner keeps the project from stalling while everyone waits for someone else.
What should I decide before my first merge?
Decide what makes two records duplicates in your CRM, and what the merged record should look like. That means choosing the primary record, such as the oldest or the one with the most data. Then choose, field by field, which value wins, especially for owner, lifecycle stage and opt-outs.
What should I do with a match that isn't a duplicate?
Reject it, once you're certain the records are separate. If your tool lets you reject a match, do it, so the match doesn't come back in later searches. Write down why it isn't a duplicate, such as a shared inbox or a regional branch, so the reason is clear to your team.


 Or sign up with Google


 HubSpot Marketplace












