

TL;DR
- Spreadsheet apps remove rows with identical values in the columns you choose.
- A script suits large or repeated imports, if someone on the team writes code.
- Data-prep apps group similar spellings, such as company names written several ways.
- Spreadsheet tools delete extra rows, so values in a deleted row are lost.
- Dedupely finds and merges duplicates inside a CSV file, so you import clean records.
A CSV import is one of the fastest ways to add records to a CRM, and one of the fastest ways to add duplicates. Event lists, purchased lists and exports from other tools rarely arrive clean.
The file can hold the same person twice, extra spaces and mixed formats. Many teams reach for whatever tool is already open, and each one handles that mess differently.
In this post, you'll see what spreadsheet apps, scripts and data-prep apps do with a file before an import. You'll also see what each one deletes, and where each one stops.
What a cleanup tool needs to handle
An import file has two kinds of problems: messy values, and the same record more than once. The tools below differ mostly in how they handle the second one, and in what happens to the data they remove.
Fix formats first, since extra spaces or mixed capitalization stop two values from matching. Then look for duplicates, starting with the field that identifies each record, like email or domain.
Spreadsheet apps
Spreadsheet apps are where many imports get checked, because everyone already has one. They handle exact duplicates well on small files.
What spreadsheet apps do
Most spreadsheet apps have a remove duplicates command. You choose which columns to compare, and the duplicate rows are deleted for good, so copy the data first.
Before removing anything, you can highlight duplicates with conditional formatting, or filter for unique records only. A trim function or command removes extra spaces, keeping single spaces between words.
Details that matter for CRM data
Some apps compare the displayed value, so the same date shown as "12/8/2017" and "Dec 8, 2017" counts as two different values. Others treat cells as duplicates even when their capitalization differs.
Trimming often leaves the nonbreaking space that gets copied from web pages. Two values that look identical can still fail to match because of it.
Where spreadsheet apps stop
Spreadsheet apps find identical values only. "Jon Smith" and "Jonathan Smith" with different emails stay as two rows.
They also delete rows and don't merge them. If the deleted row held the only phone number, that number is gone, and you may not know which row was kept.
Code: a script
For large files or imports that repeat every week, a script gives you the same result every time. Data libraries in common programming languages have a function for this.
What a script does
A remove duplicates function usually compares all columns by default, or only the columns you list. You choose whether to keep the first row, the last row or no row from each group.
Text functions such as lowercasing and stripping spaces let you clean a column before comparing it. Because the steps live in a script, the next import gets exactly the same treatment.
Where code stops
A script compares exact values, so near matches need extra logic you write yourself. Every new exception, like nicknames or company suffixes, adds code to maintain.
It also needs someone who writes code, and the next person has to understand the script.
Data-prep apps
Data-prep apps are built for cleaning messy data. Their clustering finds groups of different values that may be the same thing, like "Acme Inc" and "ACME, Inc.".
They often offer several methods, from strict ones with few false matches to phonetic and edit-distance methods that catch more variations. Clustering edits cell values so a group shares one value.
They don't merge the rows themselves, so you still remove duplicates afterward. They fit best as a step before one of the other tools.
How the tools compare
| Spreadsheet apps | A script | Data-prep apps | |
|---|---|---|---|
| Finds | Identical values | Exact values, plus any logic you write | Groups of similar values |
| Choose columns | Yes | Yes | Per column |
| Which row is kept | Often not stated | First, last or none | Not applicable: edits values |
| Merges values from both rows | No | Only with code you write | No |
| Skills needed | Spreadsheet basics | Programming | Learning the app |
How to choose a cleanup tool
The right tool depends on the file, the team and how often you import. What counts as a duplicate also differs by team, so decide that before you pick.
- A spreadsheet app fits small, one-off files where exact matches on email or domain are enough.
- A script fits large or recurring imports, when someone on the team writes and maintains code.
- A data-prep app fits files with many spelling variations in names or company fields.
- A deduplication tool fits files that need near matches and values merged from several rows.
Whatever you choose, start with the obvious duplicates: exact matches on email for people and domain for companies. Keep the original file, so you can go back to it.
Before you import, compare the row count before and after the cleanup. Then open a sample of the removed rows and check that each one was a duplicate you meant to remove.
How Dedupely cleans a CSV before an import
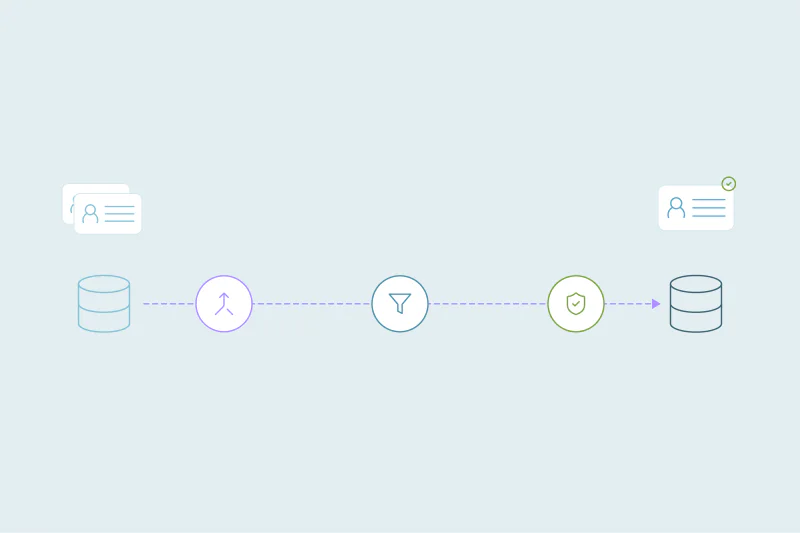
Upload the list to Dedupely, merge the duplicates inside it with rules for which value wins, and download the clean records to import. You preview each merge, and once the records are in your connected CRM, duplicates against existing records are found and merged there. CSV uploads are unlimited, and CSV records don't count toward your plan's record limit.
Pick the tool that fits the file
Spreadsheet apps, scripts and data-prep apps each solve part of an import cleanup. They fix formats and remove exact duplicates well, and they stop at near matches and at values spread across several rows.
The file is the cheapest place to fix duplicates. Nothing depends on those rows yet, so every duplicate you catch there is one you won't have to merge later.
Frequently asked questions
What's the best tool to clean a CSV before a CRM import?
It depends on the file. A spreadsheet app handles small files with exact duplicates on email or domain, and a script suits large or recurring imports if someone writes code. A data-prep app helps with spelling variations, and a deduplication tool fits files that need near matches and merged values.
Does removing duplicates in a spreadsheet delete data permanently?
Yes. A spreadsheet's remove duplicates command deletes the extra rows, so copy the original data first. You may not know which row is kept, so highlight duplicates and copy over any value that exists only in a row you'll delete.
Is removing duplicates in a spreadsheet case-sensitive?
It depends on the app. Some treat cells as duplicates even when their capitalization or formatting differs, and others compare the displayed value. Trim whitespace first, since extra spaces can stop two values from matching, and check for nonbreaking spaces that trimming leaves behind.
How do I remove duplicates from a CSV with a script?
Use your data library's remove duplicates function, which usually compares all columns and keeps the first row of each group. List only the columns to compare, such as email, and choose whether to keep the first row, the last row or none. Lowercase and strip text columns before comparing.
Can a spreadsheet find near-duplicate contacts?
Not on its own, because spreadsheet apps remove identical values, so typos, nicknames and company suffixes slip through. Cleaning formats first catches some variations, while near matches often need code or a tool built for fuzzy matching. Review a sample before importing either way.

 Or sign up with Google